Code: 54026513
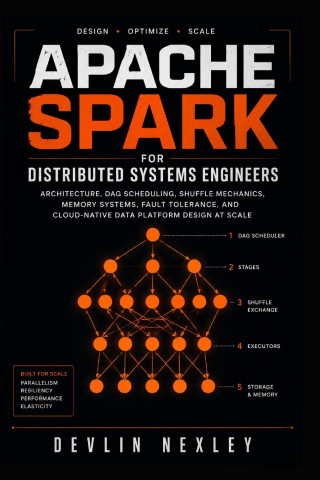
Apache Spark for Distributed Systems Engineers
by Devlin Nexley
Apache Spark is not just a data processing framework-it is a distributed execution system built on deep principles of cluster computing, DAG-based scheduling, memory-aware computation, and fault-tolerant design.This book provides ... more


- Language:
 English
- Binding: Paperback
- Number of pages: 184
Publisher: Devlin Nexley, 2026
- More about this

22.50 €
RRP: 22.52 €
You save 0.02 €

You might also like
-
Threshing Day (Wing and Claw Collection)
17.90 € -29 % -
Threshing Day (Limited Deluxe Edition)
20.60 € -29 % -
21 Days of Fear
16.20 € -27 % -
Murdoku
14.50 € -22 % -
The Art of Gravity Falls
36.50 € -25 % -
White Nights
4.49 € -14 % -
Berserk Deluxe Volume 1
38.91 € -25 % -
The Mirror of Infinite Endings
15 € -29 % -
The Long-Lived King: An Original The Owl House Graphic Novel
16.30 € -30 % -
Court of Thorns and Roses 6
15.60 € -30 % -
Berserk Deluxe Volume 2
36.50 € -28 % -
What Happened Yesterday
15.60 € -26 % -
Berserk Deluxe Volume 3
55.31 € -
Lord of Mysteries, Vol. 4: The Faceless, Part I
17 € -13 % -
Witch Hat Atelier: Grimoire Edition 1
35.10 € -29 % -
The Mirror of Infinite Endings
19 € -29 % -
Kid's Box New Generation Level 2 Activity Book with Digital Pack British English
12.30 € -
Fourth Wing
23.80 € -23 % -
Jojo's Bizarre Adventure: Part 7--Steel Ball Run, Vol. 8
18.20 € -24 % -
Iron Flame
24.80 € -20 % -
The Courage To Be Disliked
10.59 € -13 %
Give this book as a present today
- Order book and choose Gift Order.
- We will send you book gift voucher at once. You can give it out to anyone.
- Book will be send to donee, nothing more to care about.
Availability alert
Enter your e-mail address and once book will be available,
we will send you a message. It's that simple.
More about Apache Spark for Distributed Systems Engineers
You get 55 loyalty points
 Book synopsis

Apache Spark is not just a data processing framework-it is a distributed execution system built on deep principles of cluster computing, DAG-based scheduling, memory-aware computation, and fault-tolerant design.
This book provides a rigorous, systems-level examination of Spark as a production-grade distributed execution engine. It moves beyond APIs, tutorials, and surface-level usage patterns to expose the internal mechanisms that govern how Spark actually executes workloads at scale.
Designed for experienced engineers working in distributed systems, backend infrastructure, and data platform engineering, this book dissects Spark as an architectural system rather than a development tool.
Inside, you will explore how Spark transforms high-level computations into distributed execution graphs, how it schedules and coordinates work across clusters, and how it manages the complexity of large-scale data movement in cloud-native environments.
Key areas covered include:
Internal architecture of Spark's driver, executors, and cluster coordination model
DAG construction, stage decomposition, and task scheduling mechanics
Shuffle architecture, data movement patterns, and network bottlenecks
Memory management, execution optimization, and JVM runtime behavior
Fault tolerance through lineage reconstruction and retry semantics
Query execution via Spark SQL, Catalyst optimizer, and Tungsten engine
Structured Streaming and incremental computation models
Performance bottlenecks, skew handling, and production tuning strategies
Cloud-native execution on object storage systems and Kubernetes
Integration with modern lakehouse ecosystems such as Delta Lake, Iceberg, and Hudi
Rather than presenting Spark as a tool to be used, this book treats it as a distributed systems case study-revealing how large-scale data infrastructure is engineered, optimized, and operated under real production constraints.
By the end, readers will understand not only how Spark works, but why its architecture is designed the way it is, what trade-offs shape its execution model, and how it fits into the broader evolution of modern distributed data platforms.
This is a book for engineers who build systems, not just pipelines.
Book details
22.50 €
- Full title: Apache Spark for Distributed Systems Engineers
- Author: Devlin Nexley
- Language: English
- Binding: Paperback
- Number of pages: 184
- EAN: 9789326137003
- ISBN: 9326137007
- ID: 54026513
- Publisher: Devlin Nexley
- Weight: 255 g
- Dimensions: 229 × 152 × 10 mm
- Date of publishing: 24. September 2026
Collection points Bratislava a 13474 dalších
Copyright ©2008-26 najlacnejsie-knihy.sk All rights reservedPrivacyCookies

 26952 collection points
 Delivery 2.99 €
 02/210 210 99 (8-15.30h)
