Code: 01426738
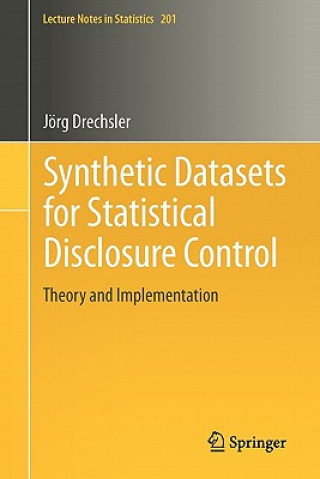
Synthetic Datasets for Statistical Disclosure Control
by Jörg Drechsler
The aim of this book is to give the reader a detailed introduction to the different approaches to generating multiply imputed synthetic datasets. It describes all approaches that have been developed so far, provides a brief histor ... more


- Language:
 English
- Binding: Paperback
- Number of pages: 138
Publisher: Springer-Verlag New York Inc., 2011
- More about this


You might also like
-
How to Make Your Electric Guitar Play Great!
22.12 € -25 % -
Third Industrial Revolution
16.08 € -25 % -
Slam Dunk (Star Edition) - Tome 1
12.76 € -
The Millicent Quibb School of Etiquette for Young Ladies of Mad Science
8.74 € -21 % -
Abandonment to Divine Providence
22.73 € -9 % -
Kapitan Nauka Gra edukacyjna Gotowanie
12.16 € -10 % -
Broken Mate
11.25 € -25 % -
Catalogue of Late Roman Coins in the Dumbarton Oaks Collection and in the Whittemore Collection: From Arcadius and Honorius to the Accession of Ana
110.52 € -
Disney Lorcana TCG Playmat Goofy
20.51 € -2 % -
Spezialverbände der Gebirgstruppe
33.38 € -16 % -
Gone Boy
14.67 € -26 % -
Councillor
13.87 € -1 % -
Extensions of First-Order Logic
91.71 € -
fascista che disse di no a Hitler. Diari
27.55 € -
National Parks 2: A Traveler's Journal
12.37 € -
MR SALTARIN
5.62 € -
Sermones 1 (1-50) : sobre el Antiguo Testamento
61.54 € -
Scale Shapes For Piano - Grade 1 (2nd Edition)
15.58 € -
Le Guide complet du propriétaire de chevaux. Choisir son cheval, l'installer, l'entretenir
29.56 € -
God of Philosophy
61.64 € -
I Love Winter (Chinese English Bilingual Children's Book - Mandarin Simplified)
16.58 € -1 % -
Voyagez au Japon
35.29 € -
Lineare Algebra kompakt fur Dummies
9.24 € -29 % -
Birmingham: The Hidden History
19 € -25 % -
Here I Am
18 € -9 % -
Популярная скрипичная музыка. Обработка для скрипки и фортепиано
10.55 € -11 % -
Der alte Helm - Eine Erzählung
15.78 € -1 % -
Arraioa hau da hau abentura
11.66 € -
Notices: Poems & Art by Susan Read Cronin
14.78 € -2 % -
Beyond Valor
19.60 € -17 % -
In Defense of Women
24.04 € -9 % -
Salmon Cookbook: Scrumptious Salmon Recipes
8.94 € -6 % -
Rum Affair
17.60 € -17 % -
Halloween Delights Journal
51.08 € -
Das große Buch der riesigen Tiere. Das kleine Buch der winzigen Tiere
14.37 € -15 %
Give this book as a present today
- Order book and choose Gift Order.
- We will send you book gift voucher at once. You can give it out to anyone.
- Book will be send to donee, nothing more to care about.
More about Synthetic Datasets for Statistical Disclosure Control
You get 316 loyalty points
 Book synopsis

The aim of this book is to give the reader a detailed introduction to the different approaches to generating multiply imputed synthetic datasets. It describes all approaches that have been developed so far, provides a brief history of synthetic datasets, and gives useful hints on how to deal with real data problems like nonresponse, skip patterns, or logical constraints. Each chapter is dedicated to one approach, first describing the general concept followed by a detailed application to a real dataset providing useful guidelines on how to implement the theory in practice. The discussed multiple imputation approaches include imputation for nonresponse, generating fully synthetic datasets, generating partially synthetic datasets, generating synthetic datasets when the original data is subject to nonresponse, and a two-stage imputation approach that helps to better address the omnipresent trade-off between analytical validity and the risk of disclosure.§The book concludes with a glimpse into the future of synthetic datasets, discussing the potential benefits and possible obstacles of the approach and ways to address the concerns of data users and their understandable discomfort with using data that doesn t consist only of the originally collected values. §The book is intended for researchers and practitioners alike. It helps the researcher to find the state of the art in synthetic data summarized in one book with full reference to all relevant papers on the topic. But it is also useful for the practitioner at the statistical agency who is considering the synthetic data approach for data dissemination in the future and wants to get familiar with the topic.§Each chapter is dedicated to one approach, first describing the general concept followed by a detailed application to a real dataset providing useful guidelines on how to implement the theory in practice. The discussed multiple imputation approaches include imputation for nonresponse, generating fully synthetic datasets, generating partially synthetic datasets, generating synthetic datasets when the original data is subject to nonresponse, and a two-stage imputation approach that helps to better address the omnipresent trade-off between analytical validity and the risk of disclosure.§The book concludes with a glimpse into the future of synthetic datasets, discussing the potential benefits and possible obstacles of the approach and ways to address the concerns of data users and their understandable discomfort with using data that doesn t consist only of the originally collected values. §The book is intended for researchers and practitioners alike. It helps the researcher to find the state of the art in synthetic data summarized in one book with full reference to all relevant papers on the topic. But it is also useful for the practitioner at the statistical agency who is considering the synthetic data approach for data dissemination in the future and wants to get familiar with the topic.§The discussed multiple imputation approaches include imputation for nonresponse, generating fully synthetic datasets, generating partially synthetic datasets, generating synthetic datasets when the original data is subject to nonresponse, and a two-stage imputation approach that helps to better address the omnipresent trade-off between analytical validity and the risk of disclosure.§The book concludes with a glimpse into the future of synthetic datasets, discussing the potential benefits and possible obstacles of the approach and ways to address the concerns of data users and their understandable discomfort with using data that doesn t consist only of the originally collected values. §The book is intended for researchers and practitioners alike. It helps the researcher to find the state of the art in synthetic data summarized in one book with full reference to all relevant papers on the topic. But it is also useful for the practitioner at the statistical agency who is considering the synthThe aim of this book is to give the reader a detailed introduction to the different approaches to generating multiply imputed synthetic datasets. It describes all approaches that have been developed so far, provides a brief history of synthetic datasets, and gives useful hints on how to deal with real data problems like nonresponse, skip patterns, or logical constraints. Each chapter is dedicated to one approach, first describing the general concept followed by a detailed application to a real dataset providing useful guidelines on how to implement the theory in practice. The discussed multiple imputation approaches include imputation for nonresponse, generating fully synthetic datasets, generating partially synthetic datasets, generating synthetic datasets when the original data is subject to nonresponse, and a two-stage imputation approach that helps to better address the omnipresent trade-off between analytical validity and the risk of disclosure.§The book concludes with a glimpse into the future of synthetic datasets, discussing the potential benefits and possible obstacles of the approach and ways to address the concerns of data users and their understandable discomfort with using data that doesn t consist only of the originally collected values. §The book is intended for researchers and practitioners alike. It helps the researcher to find the state of the art in synthetic data summarized in one book with full reference to all relevant papers on the topic. But it is also useful for the practitioner at the statistical agency who is considering the synthetic data approach for data dissemination in the future and wants to get familiar with the topic.The aim of this book is to give the reader a detailed introduction to the different approaches to generating multiply imputed synthetic datasets. It describes all approaches that have been developed so far, provides a brief history of synthetic datasets, and gives useful hints on how to deal with real data problems like nonresponse, skip patterns, or logical constraints. §Each chapter is dedicated to one approach, first describing the general concept followed by a detailed application to a real dataset providing useful guidelines on how to implement the theory in practice. §The discussed multiple imputation approaches include imputation for nonresponse, generating fully synthetic datasets, generating partially synthetic datasets, generating synthetic datasets when the original data is subject to nonresponse, and a two-stage imputation approach that helps to better address the omnipresent trade-off between analytical validity and the risk of disclosure.§The book concludes with a glimpse into the future of synthetic datasets, discussing the potential benefits and possible obstacles of the approach and ways to address the concerns of data users and their understandable discomfort with using data that doesn t consist only of the originally collected values. §The book is intended for researchers and practitioners alike. It helps the researcher to find the state of the art in synthetic data summarized in one book with full reference to all relevant papers on the topic. But it is also useful for the practitioner at the statistical agency who is considering the synthetic data approach for data dissemination in the future and wants to get familiar with the topic.
Book details
Book category Books in English Society & social sciences Sociology & anthropology Sociology
129.73 €
- Full title: Synthetic Datasets for Statistical Disclosure Control
- Subtitle: Theory and Implementation
- Author: Jörg Drechsler
- Language: English
- Binding: Paperback
- Number of pages: 138
- EAN: 9781461403258
- ISBN: 1461403251
- ID: 01426738
- Publisher: Springer-Verlag New York Inc.
- Weight: 254 g
- Dimensions: 235 × 155 × 15 mm
- Date of publishing: 26. June 2011
Trending among others
-
Eroticism
11.25 € -28 % -
Being Mortal
10.05 € -29 % -
Disappearance of Rituals
15.98 € -7 % -
Social Intelligence
14.47 € -19 % -
Birth Of A Mother
19 € -4 % -
Sociology: A Very Short Introduction
10.75 € -24 % -
Voluptuous Panic
29.16 € -24 % -
St Joseph of Arimathea at Glastonbury
19.80 € -15 % -
Railway Journey
37 € -
Making Tea, Making Japan
25.94 € -12 % -
Respect
15.88 € -25 % -
Flower and the Scorpion
40.92 € -
Fair Play Deck
18.60 € -25 % -
Gifts of Imperfection: 10th Anniversary Edition
14.77 € -29 % -
The True Believer
15.38 € -19 % -
Tragedy and Hope
32.27 € -
Surrendered Single
10.45 € -22 % -
Theory of the Leisure Class
11.46 € -25 % -
Anatomy of Love
17.49 € -10 % -
Cruel Optimism
25.33 € -9 % -
Why Love Hurts - A Sociological Explanation
17.79 € -1 % -
Introduction to Japanese Society
38.91 € -
Smoke Gets in Your Eyes
10.75 € -29 % -
Sociology Book
22.72 € -19 % -
Homo Academicus
27.65 € -11 % -
Building and Dwelling
14.77 € -27 % -
Academic Writing for Graduate Students
30.16 € -
Raising Children Compassionately
5.62 € -26 % -
Intercourse
15.08 € -25 % -
Sex at Dawn
12.16 € -30 % -
Being Mortal
15.48 € -29 % -
Craftsman
13.87 € -24 % -
Chrysanthemum and the Sword
15.98 € -
On Death and Dying
15.08 € -25 % -
Transparency Society
12.96 € -10 % -
Blueprint for Revolution
10.75 € -29 % -
Marriage, a History
15.08 € -25 % -
Expulsion of the Other - Society, Perception and Communication Today
14.37 € -6 % -
Trickster Makes This World
15.38 € -30 % -
Regretting Motherhood
17.69 € -15 % -
Wounded Woman
16.48 € -17 % -
Of Woman Born
13.67 € -25 % -
That Good Night
14.07 € -25 % -
Unexpected Joy of Being Single
12.56 € -24 % -
World-Systems Analysis
17.89 € -24 % -
Wanderlust
14.88 € -26 % -
Outsiders
13.97 € -25 % -
The Rise of the Creative Class
16.38 € -23 % -
Statistics in Corpus Linguistics
39.92 €
Collection points Bratislava a 13562 dalších
Copyright ©2008-26 najlacnejsie-knihy.sk All rights reservedPrivacyCookies

 27128 collection points
 Delivery 2.99 €
 02/210 210 99 (8-15.30h)
