Code: 19038953
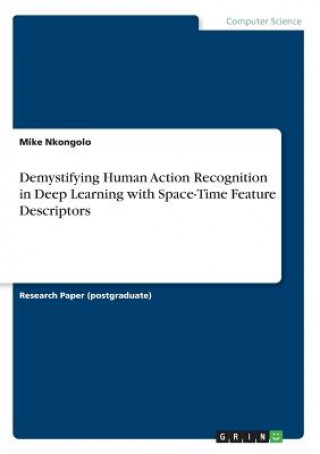
Demystifying Human Action Recognition in Deep Learning with Space-Time Feature Descriptors
by Mike Nkongolo
Research Paper (postgraduate) from the year 2018 in the subject Computer Science - Internet, New Technologies, , course: Machine Learning, language: English, abstract: Human Action Recognition is the task of recognizing a set of a ... more


- Language:
 English
- Binding: Paperback
- Number of pages: 40
Publisher: Grin Publishing, 2018
- More about this

16.12 €
RRP: 18.92 €
You save 2.79 €

In stock at our supplier
Shipping in 5 - 8 days
You might also like

Give this book as a present today
- Order book and choose Gift Order.
- We will send you book gift voucher at once. You can give it out to anyone.
- Book will be send to donee, nothing more to care about.
More about Demystifying Human Action Recognition in Deep Learning with Space-Time Feature Descriptors
You get 39 loyalty points
 Book synopsis

Research Paper (postgraduate) from the year 2018 in the subject Computer Science - Internet, New Technologies, , course: Machine Learning, language: English, abstract: Human Action Recognition is the task of recognizing a set of actions being performed in a video sequence. Reliably and efficiently detecting and identifying actions in video could have vast impacts in the surveillance, security, healthcare and entertainment spaces. The problem addressed in this paper is to explore different engineered spatial and temporal image and video features (and combinations thereof) for the purposes of Human Action Recognition, as well as explore different Deep Learning architectures for non-engineered features (and classification) that may be used in tandem with the handcrafted features. Further, comparisons between the different combinations of features will be made and the best, most discriminative feature set will be identified. In the paper, the development and implementation of a robust framework for Human Action Recognition was proposed. The motivation behind the proposed research is, firstly, the high effectiveness of gradient-based features as descriptors - such as HOG, HOF, and N-Jets - for video-based human action recognition. They are capable of capturing both the salient spatial and temporal information in the video sequences, while removing much of the redundant information that is not pertinent to the action. Combining these features in a hierarchical fashion further increases performance.
Book details
16.12 €
- Full title: Demystifying Human Action Recognition in Deep Learning with Space-Time Feature Descriptors
- Author: Mike Nkongolo
- Language: English
- Binding: Paperback
- Number of pages: 40
- EAN: 9783668642607
- ISBN: 3668642605
- ID: 19038953
- Publisher: Grin Publishing
- Weight: 72 g
- Dimensions: 210 × 148 × 2 mm
- Published: 2018
Trending among others
-
Threshing Day (Limited Deluxe Edition)
19.45 € -34 % -
Murdoku
15.01 € -21 % -
The Mirror of Infinite Endings
14.61 € -25 % -
The Long-Lived King: An Original The Owl House Graphic Novel
19.75 € -29 % -
White Nights
4.53 € -14 % -
Court of Thorns and Roses 6
15.72 € -30 % -
I'll Believe in Anything. The Making of Heated Rivalry Season 1
22.47 € -24 % -
Trust Fall
10.07 € -18 % -
The Art of Gravity Falls
37.80 € -28 % -
Cozy Countdown: An Advent Coloring Book Bundle
22.17 € -25 % -
Jojo's Bizarre Adventure: Part 7--Steel Ball Run, Vol. 9
19.25 € -22 % -
21 Days of Fear
16.73 € -27 % -
Lord of Mysteries, Vol. 4: The Faceless, Part I
16.93 € -16 % -
Berserk Deluxe Volume 1
39.01 € -27 % -
The Mirror of Infinite Endings
19.35 € -37 % -
Fourth Wing
23.89 € -27 % -
Berserk Deluxe Volume 3
55.44 € -
Iron Flame
24.89 € -24 % -
Witch Hat Atelier: Grimoire Edition 1
34.37 € -32 % -
Berserk Deluxe Volume 2
36.99 € -31 % -
Witch Hat Atelier: Grimoire Edition 2
35.18 € -30 % -
Penguin Readers Level 4: The Adventures of Sherlock Holmes (ELT Graded Reader)
10.98 € -2 % -
Murdoku Volume 2: Back in Time
15.01 € -21 % -
The Count of Monte Cristo
13.70 € -10 % -
East of Eden
12.69 € -27 % -
Escape Me Deluxe Limited Edition
19.35 € -25 % -
Once Upon a Broken Heart Collector's Edition
26.81 € -29 % -
Protocols
16.53 € -
Protocols
14.81 € -29 % -
Jojo's Bizarre Adventure: Part 7--Steel Ball Run, Vol. 2
19.25 € -22 % -
Jojo's Bizarre Adventure: Part 7--Steel Ball Run, Vol. 8
18.24 € -26 % -
The Courage To Be Disliked
10.68 € -13 % -
Protocols
29.43 € -26 % -
Jojo's Bizarre Adventure: Part 7--Steel Ball Run, Vol. 1
19.25 € -22 % -
Chainsaw Man, Vol. 22
9.47 € -25 % -
How to Win at Chess, Next Level
26.41 € -11 % -
Pokémon Deluxe Character Guide
41.13 € -28 % -
What Happened Yesterday
15.92 € -27 % -
Absolute Batman Vol. 3
19.25 € -8 % -
Berserk Deluxe Volume 4
43.45 € -19 % -
The Emperor's Enemy (Deluxe Limited Edition)
24.29 € -29 % -
Yesteryear
16.12 € -12 % -
Dungeon Crawler Carl
11.48 € -29 % -
Kid's Box New Generation Level 2 Activity Book with Digital Pack British English
10.68 € -10 % -
Fruit Fly
16.63 € -27 % -
Murdle: Volume 1
13 € -29 % -
Spooky Cutie
8.16 € -27 % -

Ready for C1 Advanced 4th Edition
27.21 € -8 % -
Restitution
9.87 € -27 %
Collection points Bratislava a 13582 dalších
Copyright ©2008-26 najlacnejsie-knihy.sk All rights reservedPrivacyCookies

 27168 collection points
 Delivery 2.99 €
 02/210 210 99 (8-15.30h)
