Code: 51948242
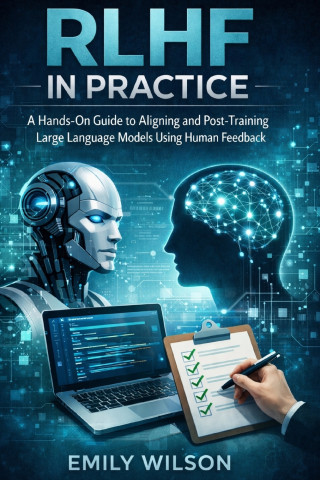
RLHF in Practice
by Emily Wilson
RLHF in Practice is the practical, no-nonsense guide that ML engineers and technical teams have been waiting for.This book takes you step-by-step through the real-world process of aligning and post-training large language models u ... more


- Language:
 English
- Binding: Paperback
- Number of pages: 320
Publisher: Independently published, 2026
- More about this

44.02 €
RRP: 47.34 €
You save 3.32 €

In stock at our supplier
Shipping in 9 - 13 days
You might also like
-
The Odyssey
15.27 € -20 %
Give this book as a present today
- Order book and choose Gift Order.
- We will send you book gift voucher at once. You can give it out to anyone.
- Book will be send to donee, nothing more to care about.
More about RLHF in Practice
You get 107 loyalty points
 Book synopsis

RLHF in Practice is the practical, no-nonsense guide that ML engineers and technical teams have been waiting for.
This book takes you step-by-step through the real-world process of aligning and post-training large language models using human feedback. Instead of abstract theory, you'll get clear explanations, honest trade-offs, and actionable strategies you can apply immediately.
You'll learn:
Why SFT is the foundation of every successful alignment pipeline - and how to do it right
How to collect high-quality human preference data that actually improves your model
When to use Direct Preference Optimization (DPO) versus full PPO - and why most teams now prefer the simpler path
How to build iterative, multi-stage pipelines that deliver reliable results
Common failure modes (reward hacking, alignment tax, over-refusal) and exactly how to debug them
Practical evaluation techniques that go beyond misleading benchmarks
Scaling realities: data, compute, and infrastructure challenges at real production scale
Ethical considerations, bias, and pluralistic alignment
Perfect for engineers who want to move beyond tutorials and build production-grade aligned LLMs without wasting time on hype or overly complex approaches.
Whether you're fine-tuning open models like Llama or Mistral derivatives, building internal tools, or preparing for large-scale deployment, this book gives you the practical knowledge and decision frameworks you need to succeed.
Book details
44.02 €
- Full title: RLHF in Practice
- Subtitle: A Hands-On Guide to Aligning and Post-Training Large Language Models Using Human Feedback
- Author: Emily Wilson
- Language: English
- Binding: Paperback
- Number of pages: 320
- EAN: 9798257374807
- ID: 51948242
- Publisher: Independently published
- Weight: 431 g
- Dimensions: 229 × 152 × 17 mm
- Date of publishing: 14. April 2026
Trending among others
-
Threshing Day (Limited Deluxe Edition)
18.69 € -30 % -
Court of Thorns and Roses 6
15.67 € -23 % -
Murdoku
7.93 € -58 % -
Cozy Countdown: An Advent Coloring Book Bundle
21.71 € -28 % -
The Mirror of Infinite Endings
14.67 € -31 % -
The Long-Lived King: An Original The Owl House Graphic Novel
19.69 € -29 % -
White Nights
4.51 € -14 % -
I'll Believe in Anything. The Making of Heated Rivalry Season 1
23.62 € -20 % -
Trust Fall
10.04 € -18 % -
Jojo's Bizarre Adventure: Part 7--Steel Ball Run, Vol. 9
19.19 € -22 % -
21 Days of Fear
16.68 € -27 % -
The Mirror of Infinite Endings
19.29 € -37 % -
Fourth Wing
23.92 € -27 % -
The Art of Gravity Falls
37.69 € -23 % -
Berserk Deluxe Volume 1
39 € -27 % -
Once Upon a Broken Heart Collector's Edition
26.73 € -29 % -
Lord of Mysteries, Vol. 4: The Faceless, Part I
16.98 € -15 % -
Iron Flame
24.92 € -24 % -
East of Eden
12.76 € -26 % -
Murdoku Volume 2: Back in Time
14.97 € -21 % -
Witch Hat Atelier: Grimoire Edition 2
35.18 € -30 % -
Berserk Deluxe Volume 3
55.38 € -
Jojo's Bizarre Adventure: Part 7--Steel Ball Run, Vol. 2
19.19 € -22 % -
Escape Me Deluxe Limited Edition
21 € -20 % -
Penguin Readers Level 4: The Adventures of Sherlock Holmes (ELT Graded Reader)
10.95 € -2 % -
The Count of Monte Cristo
13.76 € -9 % -
Chainsaw Man, Vol. 22
9.44 € -25 % -
Berserk Deluxe Volume 2
36.89 € -31 % -
How to Win at Chess, Next Level
26.43 € -11 % -
Protocols
16.48 € -
Witch Hat Atelier: Grimoire Edition 1
35.58 € -29 % -
Jojo's Bizarre Adventure: Part 7--Steel Ball Run, Vol. 1
19.19 € -22 % -
Jojo's Bizarre Adventure: Part 7--Steel Ball Run, Vol. 8
18.19 € -26 % -
Murdle: Volume 1
13.06 € -29 % -
The Courage To Be Disliked
10.65 € -13 % -
Berserk Deluxe Volume 4
43.42 € -19 % -
JoJo's Bizarre Adventure: Part 7--Steel Ball Run, Vol. 3
19.19 € -22 % -
Yesteryear
16.08 € -12 % -
Protocols
14.77 € -29 % -
What Happened Yesterday
15.97 € -27 % -
Pokémon Deluxe Character Guide
41.01 € -28 % -
Restitution
9.84 € -27 % -
Protocols
29.45 € -27 % -
Fruit Fly
16.68 € -27 % -
Dungeon Crawler Carl
11.45 € -29 % -
The Guy She Was Interested in Wasn't a Guy at All, Vol. 1
13.56 € -31 % -
Absolute Batman Vol. 3
19.29 € -8 % -
Jujutsu Kaisen, Vol. 26
10.04 € -20 % -
JoJo's Bizarre Adventure: Part 7--Steel Ball Run, Vol. 4
18.89 € -32 %
Collection points Bratislava a 13606 dalších
Copyright ©2008-26 najlacnejsie-knihy.sk All rights reservedPrivacyCookies

 27216 collection points
 Delivery 2.99 €
 02/210 210 99 (8-15.30h)
